Sora died on September 24. Generated video didn't need a TikTok, it needed a story
OpenAI shut down the Sora API on September 24. A feed of generated videos has no subject. What my players actually ask for, with production numbers.
by Yannis Achour9 min read
Contents
On September 24, OpenAI switched off the Sora API. The app had already closed at the end of April. That's the end of the brand, not of the model: Sora 2 stays inside ChatGPT for paying users. OpenAI didn't talk about money. A spokesperson explained that the team was moving to world simulation, for robotics. Keep that sentence in mind, we'll come back to it.
The money came from the press. The Wall Street Journal, late March: roughly a million dollars lost per day, according to an inside source. Appfigures: $2.1M in in-app purchases, in total, since launch. A peak of 3.3M downloads in November 2025, the month the app reached Android, then 1.1M in February. Users peaked around a million, then fell under 500,000. Disney had announced a billion-dollar investment in OpenAI, with two hundred characters licensed for Sora. The deal was never signed: Disney learned about the shutdown less than an hour before it went public, and walked away.
I'm not mocking it. Sora 2, released on September 30, 2025, was what I had been waiting for for years: coherent video, with synced sound, from one sentence. My first thought: artists were going to grab it and make crazy, unique, funny things. Then I tried it. Several minutes of waiting per clip, a price that makes you hesitate before every attempt, and my urge to explore didn't last. Clearly I wasn't the only one.
And the more numbers came out, the more one idea settled in. Progress fixes waiting and price; we saw it this very summer. What killed Sora is somewhere else: a feed of generated videos has no subject.
A feed has no memory
Sora, the app, was TikTok with made-up videos. An astronaut cat, your friend as a samurai, you laugh, you scroll. The next video has nothing to do with the last one, and none of them remembers anything. Ten seconds of spectacle, then nothing.
That holds for three weeks. A meme needs shared context to be funny; a video invented from scratch has none. The "wow" of the first days was the model's. We have all lived it with every generation of image model since 2022: it wears off in a week.
My thesis fits in one sentence. A generated video is only worth something if it has a before: a character you know, a place you've already been, an object you know the history of. It needs a memory, and the video model doesn't provide one.
Faster than playback
The summer went fast. MiniMax released H3 on July 31: video with stereo sound, up to fifteen seconds. In late August, fal published a post-trained version, H3 Max, then a Turbo version in mid-September; that's the one I use to animate dialogue scenes. On September 1, vLLM showed FastH3: ten seconds of video with sound, rendered in 8.7 seconds. On eight B300 GPUs, but still. The symbolic line has been crossed: we generate faster than we watch.
It isn't real time yet, in the sense of a stream that reacts while it plays. Meta is getting close: at Connect, on September 23, Muse announced an avatar you'll be able to video-chat with, at about 870 milliseconds of latency. "Coming soon", no date.
I spent a good part of the week wondering what this changes for a game like mine. Provisional answer: it removes the wait, and that's about it.
What stays hard is consistency over time. Ten seconds generated in ten seconds, great. Ten more seconds where the same woman has the same eyes, the same scar, the coat she traded for a cloak in chapter 3: another matter. And an hour later, the pedlar who was given the brass bell has to wear it on his belt, even though nobody wrote "pedlar with a bell" in the prompt. The video model has no idea. The story does.
That's what I spent two ninety-day runs measuring on text, and I wrote about the pain here. Text is the easy case. An invented name that has to come back word for word after three months cost me nights. An invented face that has to come back feature for feature, on a model that has never seen it, is the same problem at a much higher price.
What I see in my own game
Miraviel's narrator writes text. When a scene deserves it, a fast LLM turns it into a prompt and a fast image model draws it. By default, only key scenes are illustrated: an arrival, a character whose appearance changes, a change of mood. Voice and video are one tap away, never automatic.
I was about to write that players don't ask for video. Then I opened the cost ledger.
Since September 18, when the current defaults shipped, 104 players have played 2,595 rounds (my account and test accounts excluded). 41 of them asked for at least one clip. 39%. Video is 38% of what they cost, more than text (35%) and images (23%).
So yes, they want it. The interesting question is when.
Players don't want a random clip. They ask for one when there is a before.
Prices say the same thing, the other way round:
| Unit | Cost | In narrator turns |
|---|---|---|
| One narrator turn | $0.0042 | 1 |
| One full round (narrator, scene direction, world state) | $0.0124 | ≈ 3 |
| One image (safety check included) | $0.0038 | ≈ 1 |
| One video clip, average across engines | $0.129 | ≈ 30 |
| One 5-second H3 clip | $0.20 | ≈ 48 |
An image costs about one narrator turn. A clip costs thirty. My 90-day re-certification run is 540 messages and 2,239 scenes; the narrator read about 19,000 tokens per message there, 57% of them from cache. At today's prices, the text of that run costs about $7, the key-scene images about $4. One video per scene: around $290. Nobody will pay that for a story, and I doubt anyone wants it.
And then there's this feedback, received on September 23. I quote it in full, because the first sentence matters as much as the second:
"This is the best visualisation of any CYOA game I've ever seen. […] even without the image and video gen, reserving it for the map generation and rare story-beats, this would be insanely popular."
The same player finds the images great and says we could almost do without them. I don't think that's a contradiction. They want to see their story at the moments that matter. An image every six scenes is noise. An image when lightning splits the pear tree and the cracked green cup is on the table is a memory. And to know which moment matters, you need a memory that knows what changed.
The fourteen images in my previous post were generated afterwards, on the run's real scenes, by the game's own pipeline: $0.05. Fourteen images for ninety days of story. That's roughly the ratio of a memory: a few sharp images, a lot of text around them.
2029, a story that films itself
Here is where I think this goes. It's an extrapolation; I found no serious projection to cite.
In mid-2025, ten seconds of Veo 3 cost about $7.50 through the API. In September 2026, ten seconds of H3 Max at 768p cost about $0.40. Twenty times cheaper in fifteen months, at not-quite-comparable quality. In my game, a clip still costs thirty to fifty times an image. At the current pace, the gap closes around 2028 or 2029. World models are moving in parallel: World Labs presented Atlas in September, and ByteDance is reportedly preparing a real-time world model for October, according to Bloomberg. And OpenAI, as we saw, is sending the Sora team there.
Rendering won't be the bottleneck anymore. The bottleneck will be what the renderer needs to know. At every shot, a story that films itself has to answer a few questions: who is there, what they look like today (not in chapter 1), what's in the room and what's no longer there, who knows what. Those are, give or take, the dimensions I test on text. Video just raises the price.
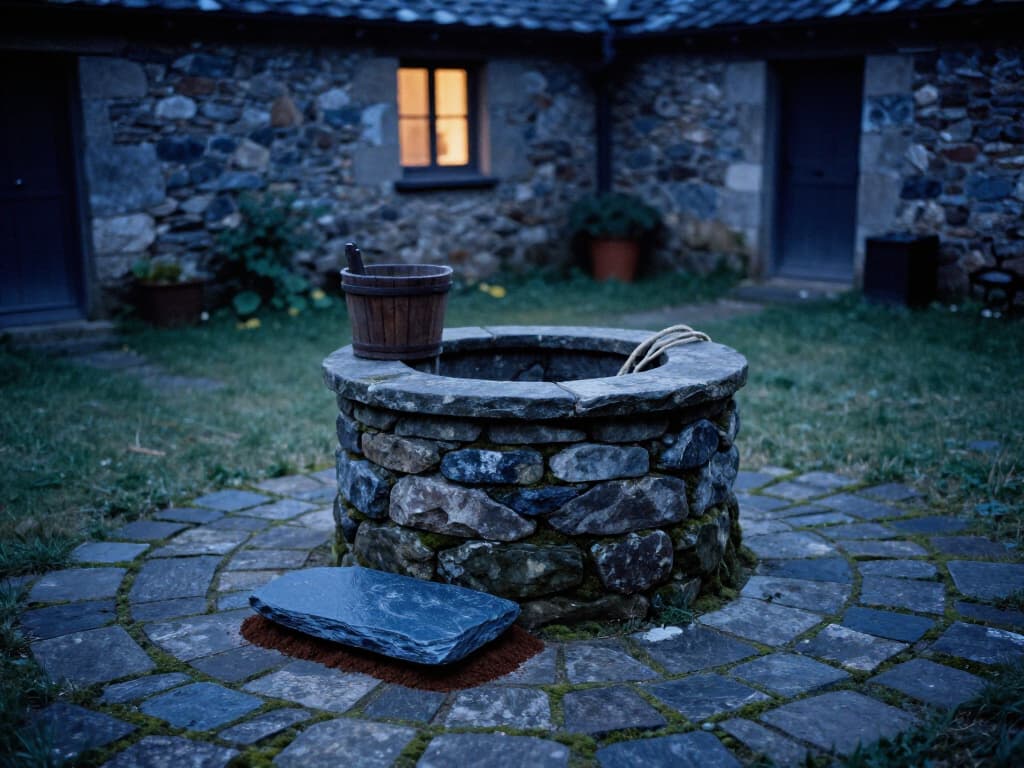
The scene I picture: you come back to a story you started four months ago. First shot, before you type anything: the well, and the blue flagstone slightly out of place. Nobody explains anything. Only you know what's underneath. The story remembered something you did with no witness, and it shows it to you without saying it. That's reminiscence by place, in pictures. In text, it's precisely the dimension where I still fail: one probe out of seven surfaced on my last full run. In video, it's the test that will separate everyone.
What breaks, first: the false memory in pictures. In text, a narrator that invents a name (Eldric, in my case) produces a false memory that consolidation then records as true. I measured it, then fixed it. In video, the model invents all the time: every shot is a reconstruction, every face an approximation. If the memory starts learning from its own images, it learns hallucinations by the thousands. A story that films itself has to remember what happened, not what it showed. I don't know anyone who has solved that, me included.
Then: the feed comes back through the window. As soon as video costs nothing, the temptation is to show everything, and we rebuild Sora, inside a story this time. The safeguard isn't technical, it's an author's choice: only show what has a before.
What I don't know
I don't know whether roleplay players will want video everywhere. Text has an advantage I often underestimate: the reader renders it in their head, and never gets the character's face wrong, since it's theirs. My numbers say players want video at certain moments. Not that they want it all the time.
I don't know how to measure visual consistency over time. My memory protocol has probes for text; I have nothing that says "this face is the same as thirty days ago". Today I have character LoRAs: they hold a face, at the cost of variety, and two LoRAs in the same image still blend. It's probably the next dimension to add. I don't have the method.
And I don't know whether Sora is a counter-example or a forerunner. OpenAI may simply have dropped a product that cost too much to focus on business and productivity; that's what the WSJ reported in March. What's certain is that the next one who wants to sell generated video to the general public will have to answer a question Sora never asked itself: what is this video a memory of?
Frequently asked questions
Why did OpenAI shut down Sora?
OpenAI gave no financial reason. A spokesperson said the team was moving to world-simulation research for robotics. According to the WSJ, the app was losing about a million dollars a day; according to Appfigures, it made $2.1M in in-app purchases in total.
Does video that renders faster than playback change anything for interactive fiction?
It removes the wait. It doesn't tell the model who is in the room, what the character is wearing today or what has gone missing since yesterday. The story's memory knows that.
Does Miraviel generate a video for every scene?
No. By default only key scenes are illustrated, and video and voice are one tap away. Since September 18, 39% of players have asked for at least one clip, usually after several rounds of story.
Sources
- 01What to know about the Sora discontinuation — OpenAI Help Center — help.openai.com, September 24, 2026
- 02Sora 2 is here — OpenAI — openai.com, September 30, 2025
- 03OpenAI's Sora was the creepiest app on your phone. Now it's shutting down — TechCrunch — techcrunch.com, March 24, 2026
- 04The sudden fall of OpenAI's most hyped product since ChatGPT — The Wall Street Journal — wsj.com, March 29, 2026
- 05OpenAI's Sora app is struggling after its stellar launch (données Appfigures) — TechCrunch — techcrunch.com, January 29, 2026
- 06Sora shut down, Disney investment off — Deadline — deadline.com, March 24, 2026
- 07OpenAI to cut back on side projects to focus on core business, WSJ reports — Reuters — tradingview.com, March 16, 2026
- 08MiniMax H3 — MiniMax — minimax.io, July 31, 2026
- 09Introducing H3 Max — fal — blog.fal.ai, August 27, 2026
- 10Serving MiniMax H3 in production (FastH3) — vLLM — vllm.ai, September 1, 2026
- 11Everything new coming to Meta's AI agent Muse — TechCrunch — techcrunch.com, September 23, 2026
- 12ByteDance founder joins AI elite in race to perfect world models — Bloomberg — bloomberg.com, September 7, 2026
- 13Veo 3 and Veo 3 Fast: new pricing — Google for Developers — developers.googleblog.com, September 8, 2025
- 14How we test memory (documentation technique) — miraviel.app, September 2, 2026
This article is also available in French. English is the main version. Read this article in French →